Building the Knowledge Base Your AI Chat Needs
Which content an AI chat really needs: how to structure, curate and keep FAQs, prices, processes and policies up to date so answers stay reliable.
In plain language
Many customers find no fitting answer in self-service. The reason is mostly the content, not the language model. A good knowledge base holds questions and answers, prices, steps, rules, facts on products and ways to get in touch. Each block answers just one question and makes sense on its own. Each statement has one source that counts, and old versions are removed. Blocks use the words customers use. A list states which topics the assistant does not answer and passes to a person. A small, well kept knowledge base answers better than a large one that nobody looks after.
An AI chat assistant is only ever as good as the content it answers from. The underlying mechanics, how a model finds relevant passages and binds its answer to them, are covered in our article on the source-grounded knowledge base with RAG. This guide sits one layer earlier: it describes which content belongs in a knowledge base, how it should be structured and how to keep it current. That is exactly where self-service most often fails in practice. Only 14 percent (Gartner) of customer issues are fully resolved in self-service, and the most common reason for failure is that in 43 percent (Gartner) of cases customers cannot find content relevant to their issue. An assistant can be as sophisticated as you like: if the right content is missing, or buried out of reach, the question stays open. This article shows which content types a knowledge base needs, in what structure an assistant can use them, and how a one-off collection becomes a maintained, living system.

Labels in the illustration
- Building blocks of the knowledge base
- FAQ & questions
- Prices & terms
- Processes & steps
- Policies & rules
- Product & service
- Contact & handover
- A curated knowledge block
- What does shipping cost?
- Standard shipping 4.90 euro,
- free from 50 euro.
- Source: price list
- Current: July
- Structure beats volume
- Users scan the page (79%)
- Words read on average (28%)
- Short, self-contained answers
- instead of long prose.
- Maintenance cycle
- Review
- Update
- Extend
- Gaps found in conversation analytics
- feed back into upkeep.
- Top reason self-service fails: no relevant content (43 percent of cases) · structure and upkeep decide
Why the Content Decides Answer Quality
With an AI assistant, attention often goes to the language model. In practice, though, the foundation decides whether an answer helps: the content the assistant draws on. The self-service numbers make this clear. While 73 percent (Gartner) of customers use a self-service channel at some point in resolving their issue, even for issues rated very simple only 36 percent (Gartner) are fully resolved without human help. The gap rarely comes from the model and mostly from the content: it is missing, outdated, contradictory or phrased so that search passes it by.
Commercially, a weak knowledge base costs twice. If a visitor finds no answer, they switch to a more expensive channel such as phone or email, or they leave entirely. In an online shop, an abandonment often means a lost sale, as our article on recovering abandoned carts in chat shows. Conversely, a well-maintained knowledge base noticeably relieves the team because recurring questions are answered reliably and automatically, as the article on the support assistant describes. Good content is therefore not a nice extra but the actual lever.
Which Content a Knowledge Base Needs
A knowledge base is not a dumping ground for text but a deliberately assembled collection. In most projects the required content falls into a few categories. This structure helps to spot gaps and to distribute maintenance. The following six building blocks form the core of almost every knowledge base for a customer-facing assistant.
-
FAQs and common questions
The questions actually asked, with clear, short answers. They form the backbone and cover a large share of recurring issues.
-
Prices and terms
Prices, shipping costs, payment methods, discounts and contract terms. Especially time-critical, because outdated figures here lead straight to wrong information.
-
Processes and steps
Ordering, delivery, returns, booking, onboarding. Described step by step so the assistant reliably guides through a procedure.
-
Policies and rules
Warranty, right of withdrawal, data protection, terms of use. Binding statements that must match the legal documents exactly.
-
Product and service info
Features, use cases, compatibility and boundaries. The basis for advice and fitting recommendations in the conversation.
-
Contact and limits
When and how to hand over to a human, which topics the assistant does not answer and which routes lead to a contact.
Which of these blocks are filled first and in most detail should follow the real questions of visitors, not gut feeling. A good source for this is the anonymized conversation analytics: they show which topics are actually asked about and where answers are missing. That way the knowledge base grows where it adds the most value, rather than on rarely asked edge cases. With a shop assistant, prices, availability and shipping come to the fore; with a service provider, it is more about processes and appointment questions.
Structure Beats Volume
For answer quality, the form of the content matters almost as much as its presence. People mostly do not read the web linearly, they scan: in user tests, 79 percent (Nielsen Norman Group) of participants scanned every new page, and only 16 percent (Nielsen Norman Group) read word by word. An average page visit also leaves time to read at most 28 percent (Nielsen Norman Group) of the words. What holds for human readers has a technical counterpart: a retrieval system also finds an answer more easily when it exists as a clearly bounded, self-contained block rather than scattered through long prose.
In practice this means breaking content into small, self-contained units that each answer one question fully. A good rule of thumb is that every block can stand on its own, without the context of the surrounding page. Meaningful headings, unambiguous terms and consistent vocabulary further raise the hit rate, because the same thing is not named one way here and another way there.
- One question per block, answered fully and without relying on surrounding context
- Meaningful headings that name the topic instead of paraphrasing it
- Consistent terms for the same thing, even across pages
- Short paragraphs and lists instead of long text blocks
- Concrete values such as deadlines, prices and quantities clearly marked
- Add synonyms and typical user phrasings so search catches them
From Raw Text to a Curated Block
Existing content is rarely already in the right form. Website copy, quotes, internal manuals and email templates hold a lot of knowledge, but mixed with marketing, duplication and outdated material. Curation means shaping clean, unambiguous blocks from this raw material. A central step is to define a leading source for each statement. If a price appears in three places with slight differences, you decide which one applies and remove the others. Contradictions in the source material are among the most common causes of wrong information (project experience).
| Aspect | Weak knowledge block | Curated knowledge block |
|---|---|---|
| Scope | Long combined text on several topics | One question, one complete answer |
| Clarity | Several slightly diverging versions | One leading, binding source |
| Language | Internal jargon and item numbers | Terms people really ask with |
| Freshness | No recognisable status | With ownership and a review date |
| Findability | Buried in prose | Clear heading and key terms |
Curation also means deciding deliberately what does not belong in. Speculative statements, commitments without backing and content on topics that a human should fundamentally answer stay out. Which actions an assistant may perform at all and where clear limits apply is set out in the article on tool control. This turns scattered raw material into a manageable, reliable set that can actually be maintained.
Defining Tone and Limits
A knowledge base is not only about what the assistant says, but also how. Tone, form of address and the handling of sensitive topics are best defined in advance and stored in the content. Just as important are the limits: topics such as law, health, binding commitments or complaints should be handed over to a human by design, rather than answered automatically. A clean handover with full conversation context is covered in the article on handover to staff.
Limits are part of the knowledge
A good register of limits is as valuable as the answers themselves. It records which topics the assistant handles on its own, where it explicitly defers and with what wording it does so. That keeps information reliable, and no one receives an invented answer to a question that a human should really answer.
A knowledge base defines not only what an assistant answers, but just as clearly what it deliberately leaves open and passes to a human.
Freshness: The Knowledge Base as a Living System
A correctly stored answer becomes worthless the moment the underlying information goes out of date. An old price, an expired promotion or a changed opening time are then reproduced cleanly but wrongly. That is why a knowledge base is not a one-off project but an ongoing process. How high the effort for finding information otherwise runs is shown by an analysis: knowledge workers typically spend 19 percent (McKinsey) of their working hours searching for and gathering information. A maintained knowledge base wins back part of that time by bundling answers in one place.
In practice, maintenance means regularly reconciling the knowledge base with the living sources: website, catalog, prices and documents. Outdated blocks are actively retired so the assistant does not answer from an old version. Time-critical figures such as prices, deadlines and availability deserve particular attention. How content can be linked technically to existing systems so changes need not be maintained twice is described in the article on integration. At XICBOT this reconciliation, the maintenance and hosting in Germany are part of the ongoing service.
- Fixed review intervals per content type, short for prices, longer for principles
- One responsible person per area so maintenance does not stall
- Actively remove outdated blocks instead of only adding new ones
- Close recognised knowledge gaps from conversation analytics on purpose
- Store new promotions, products and rules before they go live
- Spot-check against the leading source to notice contradictions early
Common Mistakes When Building It
Many knowledge bases fail not from a lack of effort but from avoidable patterns. The most common is volume over selection: a whole mountain of documents is loaded without curating it, and the assistant finds no clear answer between redundancies and contradictions. It is no coincidence that the most common reason for failed self-service is that in 43 percent (Gartner) of cases customers cannot find content relevant to their issue.
- Load everything, curate nothing: redundancies and contradictions remain
- No leading source per statement, so versions contradict each other
- Content in internal language that misses the real user questions
- No review rhythm, so prices and deadlines quietly go stale
- No defined limits, so sensitive topics get answered automatically
- Recognised gaps are not fed back into maintenance
How We Build Your Knowledge Base
It starts with a stocktake: website, shop, prices, FAQs and documents are reviewed and brought together into a structured knowledge base. Then we define a leading source for each statement, phrase the blocks in understandable language and set the limits for sensitive topics. The entry point is usually a website assistant that answers questions from the knowledge base and captures contacts, and can later be extended with shop functions, appointment requests and further actions. Because the same knowledge base serves several languages, the assistant answers consistently even when visitors ask in their own language, as the article on the multilingual assistant shows.
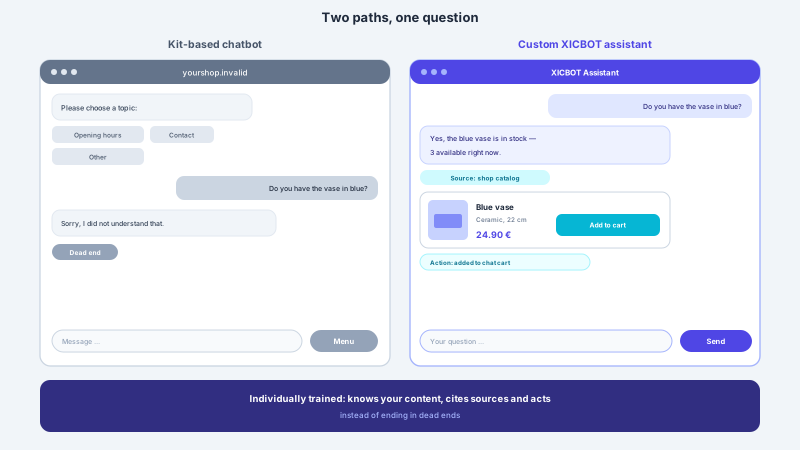
Digital-first channels such as self-service and guided chat are set, according to a survey, to be among the most important customer service tools by 2027 (Gartner). Their value stands or falls with the foundation they draw on. How an individually trained assistant fundamentally differs from a template bot is explored in the comparison custom assistant versus standard chatbot. Which package fits your plan and what a free demo for your own website looks like is shown on the pricing overview.
Frequent questions
Which content should go into a knowledge base first?
It starts with the questions actually asked. In almost every project the core is formed by FAQs, prices and terms, processes such as ordering and returns, binding policies, product or service info, and clearly defined contact and handover routes. Which of these blocks is filled first and in most detail should follow the real concerns of visitors. Anonymized conversation analytics show which topics are genuinely asked about, so the knowledge base grows where it adds the most value.
How does this differ from the topic of RAG?
RAG describes the technical mechanics of how an assistant finds relevant passages in your content and binds its answer to them, complemented by confidence thresholds and handover to humans. This guide covers the editorial side of the same task: which content belongs in the knowledge base, how it is structured and how it is kept current. The two interlock, because even the best retrieval mechanics do not help if the right content does not exist or is outdated.
How should content be structured so the assistant uses it?
Ideally in small, self-contained blocks that each answer one question fully, without assuming the context of the surrounding page. Meaningful headings, consistent terms and typical user phrasings raise the hit rate. This also matches human behaviour, since most users scan pages and read only a small share of the words (Nielsen Norman Group). Short, clearly labelled units are found more easily by both people and the retrieval system.
How often does a knowledge base need updating?
That depends on the content type. Time-critical figures such as prices, deadlines, promotions and availability should have short review intervals; foundational content such as policies longer ones. It helps to have one responsible person per area and a fixed rhythm in which the knowledge base is reconciled with the living sources and outdated material is retired. At XICBOT this reconciliation, the maintenance and hosting in Germany are part of the ongoing service.
Is a larger knowledge base automatically better?
No. Loading as many documents as possible feels thorough but often worsens the result, because duplication, outdated versions and internal jargon hamper retrieval and encourage contradictory information. A smaller, cleanly curated knowledge base with one leading source per statement usually delivers more reliable answers. It is no coincidence that missing or unfindable content is the most cited reason for failed self-service (Gartner).
What if a question is not in the knowledge base?
Then the assistant should not guess but know its limit and hand over to a human, with full conversation context. A knowledge base therefore includes a register of the topics the assistant deliberately leaves open, such as law, health or binding commitments. Every recognised gap is at the same time a cue for maintenance: it shows where content is missing and can be closed on purpose via conversation analytics, so the knowledge base grows with the real questions.
Ask it yourself, Assistant of this website
Automated assistant